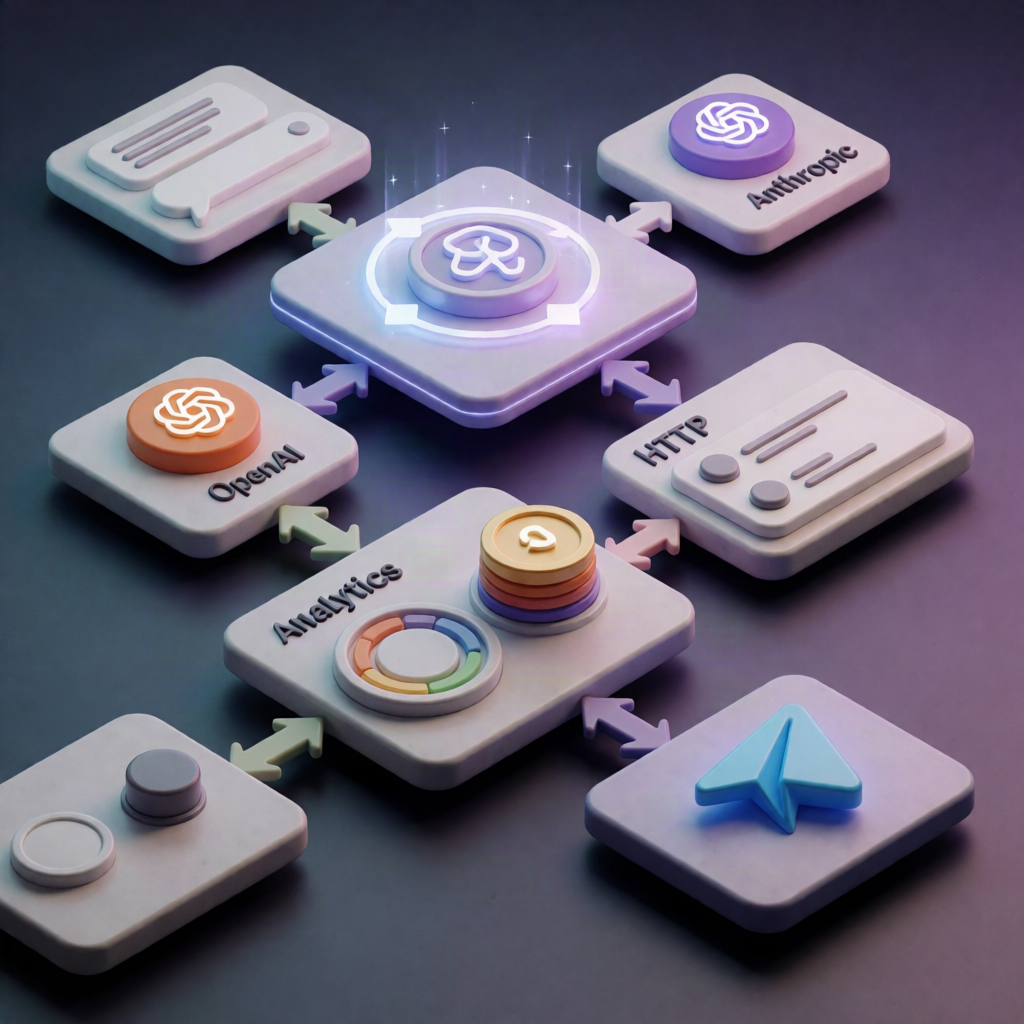
n8n LLM Retry Workflow: OpenAI + Anthropic Cost Logging
n8n LLM Retry Workflow: OpenAI + Anthropic Cost Logging
Regular price
£36.99
Regular price
£36.99
Sale price
Unit price
per
⬇
Instant Digital Download
∞
Unlimited Downloads
★
Lifetime Access in Your Account
Couldn't load pickup availability
🔥
128+ Sold
Popular with n8n builders
⚡
23 people viewing
High interest right now
✅
9 added today
Fast-moving digital product

n8n LLM Retry Workflow: OpenAI + Anthropic Cost Logging
Regular price
£36.99
Regular price
£36.99
Sale price
Unit price
per
Automatic LLM retries with OpenAI → Anthropic fallback, cost logging, and Telegram alerts
This n8n workflow automatically retries OpenAI calls, falls back to Anthropic when needed, logs token/cost estimates to an n8n Data Table, and notifies you via Telegram if every provider fails.
What this workflow does
- Triggers from n8n Chat or another workflow by accepting a user prompt and an optional system prompt.
- Sends the request to the active LLM provider (OpenAI primary), building provider-specific request parameters including model and max token settings.
- Extracts the response and usage from the HTTP result, capturing the answer, token usage, and any error details.
- Retries failures safely for rate limits, server errors, and timeouts using exponential backoff (including honoring a Retry-After header when present).
- Falls back to Anthropic after retries are exhausted or when encountering non-retryable errors.
- Returns a complete result payload including success status, provider/model used, number of attempts, latency, token totals, estimated cost, and an attempt history log.
- Logs every run by ensuring the llm_call_log n8n Data Table exists and writing one log row per execution with token and cost estimates.
- Alerts on total failure by sending a Telegram message if both OpenAI and Anthropic fail before returning the final result to the caller.
Use cases
- Harden an n8n chatbot so transient OpenAI errors don’t break conversations.
- Run cost-aware LLM automation for SaaS operations where token visibility matters.
- Provide reliability for production workflows by switching to Anthropic automatically.
Technical details
- Providers: OpenAI (primary) and Anthropic (fallback) via their API credentials.
- Core logic nodes: if, set, code, wait, switch.
- Notifications: Telegram alert on total provider failure.
- Logging: writes per-run entries to the llm_call_log n8n Data Table.
Setup note: Add OpenAI and Anthropic credentials to enable primary and fallback calls. If you don’t need storage, you can change/remove the Data Table logging steps.